How-To
l 5min

How to Build an Arabic Voice Agent with Pipecat (2026 Guide)

Arabic Voice AI
Author
Rym Bachouche

Powering the Future with AI

Join our newsletter for insights on cutting-edge technology built in the UAE

Key Takeaways

1

Pipecat simplifies real-time voice-agent development: Developers can build a pipeline connecting audio transport, Munsit STT, an LLM, and Munsit TTS to create conversational Arabic voice experiences.

2

Munsit supports the complete Arabic voice layer: The Pipecat plugin provides both speech recognition and speech synthesis, allowing developers to use Munsit for both sides of the conversation.

3

Voice output can be customized: Developers can select different voices and adjust speed, stability, sample rate, and models. These settings can also be updated while the conversation is running.

4

Streaming improves conversational flow: Faseeh TTS streams audio as it becomes available, allowing the agent to begin speaking without waiting for the entire response to finish rendering.

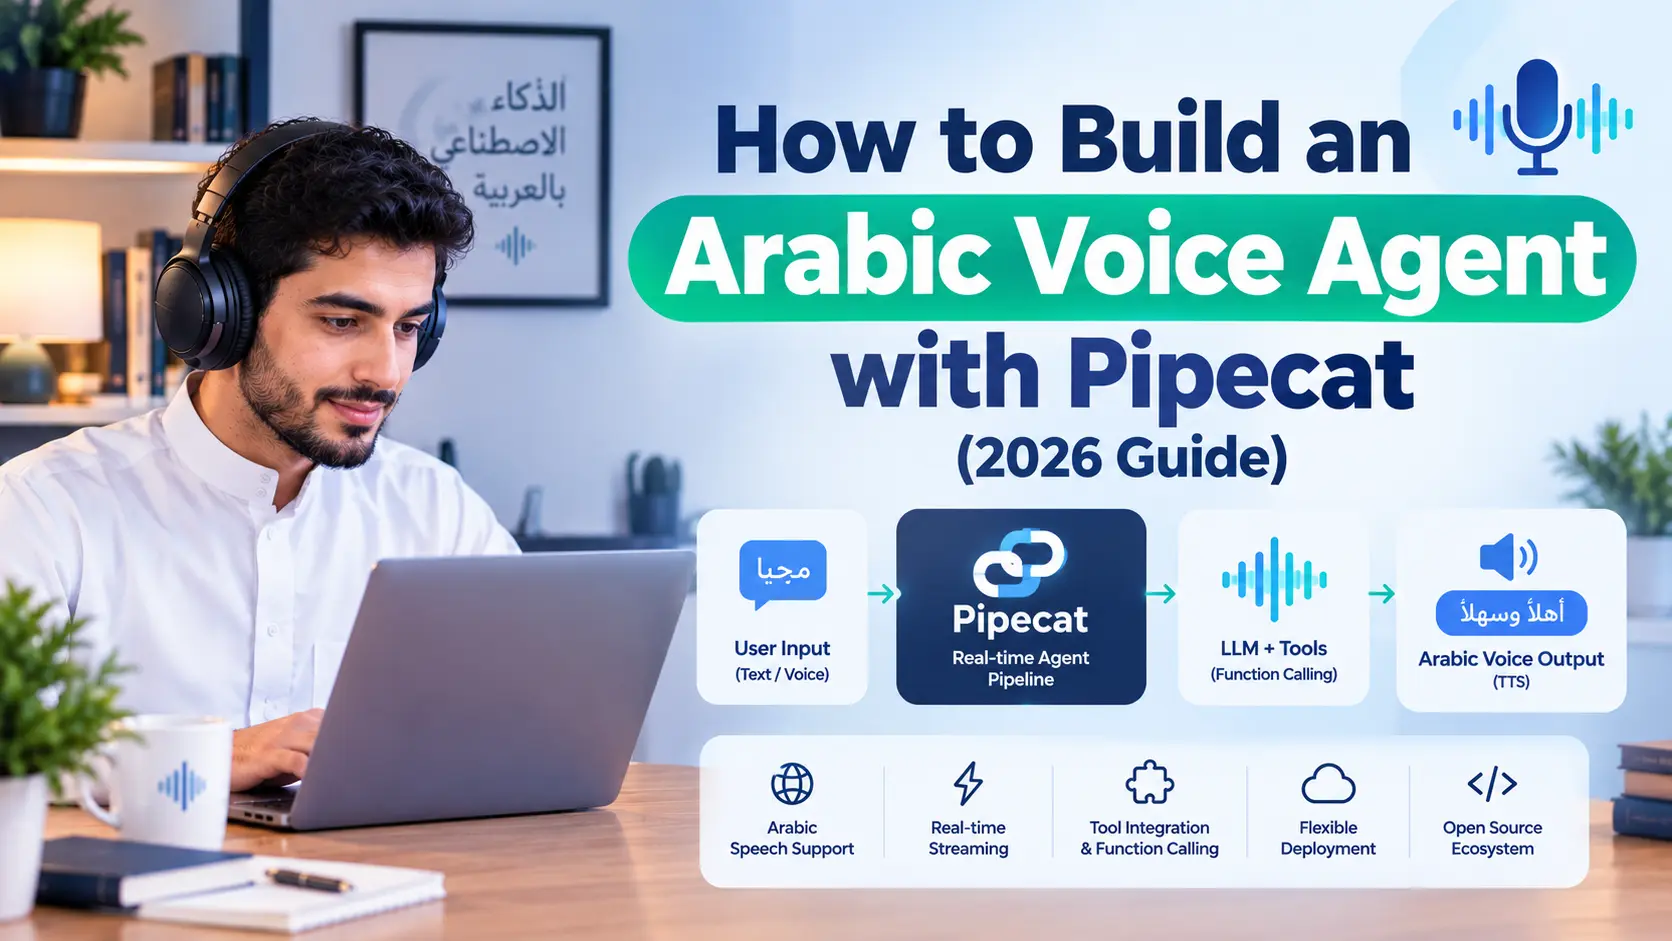
The article shows developers how to build an Arabic voice agent using Pipecat, Munsit’s Arabic speech-to-text and text-to-speech services, and an LLM. It explains how audio moves through the pipeline—from the user’s microphone to Munsit STT, the LLM, Munsit TTS, and finally back to the user as streaming Arabic speech.

The guide covers installing the Munsit Pipecat plugin, setting up API credentials, creating the agent, configuring Daily WebRTC transport, and customizing TTS settings such as voice, speed, stability, and sample rate. It also explains how developers can update voice settings during an active conversation.

‍

How to Build an Arabic Voice Agent with Pipecat

A voice agent has to solve a pipeline problem before it solves a prompting problem: speech has to become text fast enough to feel conversational, a language model has to reason over that text, and the reply has to become speech again without a noticeable gap. For Arabic specifically, callers routinely mix Arabic and English mid-sentence, and a generic multilingual STT model handles that switch by treating it as two separate recognition tasks  producing seams and errors exactly where the conversation matters most.

This guide walks through building an Arabic voice agent on Pipecat  the open-source Python framework for real-time voice and multimodal conversational agents, created and maintained by Daily, Inc. with the Pipecat developer community  using Munsit’s pipecat-plugins-munsit package, which provides both Arabic speech-to-text (live WebSocket streaming) and text-to-speech (HTTP streaming) for Arabic, including Arabic-English code-switching, from a single vendor.

‍

This is some text inside of a div block.

Architecture: What You’re Building

A Pipecat agent is built as a Pipeline of processors that frames of data move through in sequence. For a voice agent, that sequence is: microphone → transport → Munsit STT → LLM → Munsit TTS → transport → speaker. The caller speaks; the transport (this guide uses Daily’s WebRTC transport, the one documented in Munsit’s own Pipecat integration guide) captures the audio; Munsit’s STT service converts it to text; an LLM generates a reply; Munsit’s TTS service converts that reply to streaming Arabic audio  PCM16 at 24 kHz  and the transport plays it back. Pipecat’s TTSService base class aggregates LLM tokens into complete sentences before calling Munsit, so each sentence becomes one HTTP streaming request, with PCM16 chunks yielded back to the pipeline as they arrive.
‍

Prerequisites
‍

•             Python 3.9 or later

•             A Munsit account and an API key (generated from Munsit’s API Keys dashboard)

•             A Daily account and API key, if you use Daily as your WebRTC transport (Pipecat supports other transports too)

•             An LLM provider key (this guide uses OpenAI’s GPT-4o, but any Pipecat-supported LLM service will work)
‍

Step 1: Install and Authenticate
‍

pip install pipecat-plugins-munsit

Your Munsit API key is shown only once at creation  save it securely as the MUNSIT_API_KEY environment variable rather than hardcoding it. The plugin’s TTS service also expects a shared aiohttp session rather than opening its own connection per request:

import aiohttp
from pipecat_plugins_faseeh import FaseehTTSService

async with aiohttp.ClientSession() as session:
tts = FaseehTTSService(
    api_key="your-api-key",
        aiohttp_session=session,
)

Keep MUNSIT_API_KEY (and DAILY_API_KEY, OPENAI_API_KEY) out of version control; load them from environment variables or a .env file via python-dotenv in production.
‍

Step 2: Write the Agent


A complete Daily-transported agent auto-creates a Daily room, wires Munsit STT → GPT-4o → Munsit TTS, and greets the caller as soon as they join:

import asyncio
import os

import aiohttp
from dotenv import load_dotenv

from pipecat.audio.vad.silero import SileroVADAnalyzer
from pipecat.frames.frames import EndFrame, LLMMessagesUpdateFrame
from pipecat.pipeline.pipeline import Pipeline
from pipecat.pipeline.runner import PipelineRunner
from pipecat.pipeline.task import PipelineParams, PipelineTask
from pipecat.processors.aggregators.llm_context import LLMContext
from pipecat.processors.aggregators.llm_response_universal import (
    LLMContextAggregatorPair,
    LLMUserAggregatorParams,
)
from pipecat_plugins_munsit import MunsitSTTService
from pipecat.services.openai.llm import OpenAILLMService
from pipecat.transports.daily.transport import DailyParams, DailyTransport
from pipecat_plugins_faseeh import FaseehTTSService

load_dotenv(override=True)

async def main():
async with aiohttp.ClientSession() as session:
    # Auto-create a Daily room
    from pipecat.transports.daily.utils import DailyRESTHelper, DailyRoomParams

        daily_helper = DailyRESTHelper(
            daily_api_key=os.getenv("DAILY_API_KEY", ""),
            aiohttp_session=session,
    )
    room = await daily_helper.create_room(DailyRoomParams())
    token = await daily_helper.get_token(room.url)

    transport = DailyTransport(
            room.url,
        token,
        "Munsit Bot",
            DailyParams(
                audio_in_enabled=True,
                audio_out_enabled=True,
                audio_out_sample_rate=48000,
        ),
    )

    stt = MunsitSTTService(api_key=os.getenv("MUNSIT_API_KEY", ""))
    llm = OpenAILLMService(api_key=os.getenv("OPENAI_API_KEY", ""), model="gpt-4o")
    tts = FaseehTTSService(
        api_key=os.getenv("MUNSIT_API_KEY"),
            aiohttp_session=session,
    )

    messages = [
        {
            "role": "system",
            "content": "You are a helpful Arabic-speaking assistant. Respond in Arabic.",
        }
    ]
    context = LLMContext(messages=messages)
        context_aggregator = LLMContextAggregatorPair(
            context,
            user_params=LLMUserAggregatorParams(vad_analyzer=SileroVADAnalyzer()),
    )

    pipeline = Pipeline([
            transport.input(),
        stt,
            context_aggregator.user(),
        llm,
        tts,
            transport.output(),
            context_aggregator.assistant(),
    ])

    task = PipelineTask(pipeline, params=PipelineParams(allow_interruptions=True))

    @transport.event_handler("on_first_participant_joined")
    async def on_joined(transport, participant):
        await task.queue_frames([LLMMessagesUpdateFrame(messages, run_llm=True)])

    @transport.event_handler("on_participant_left")
    async def on_left(transport, participant, reason):
        await task.queue_frame(EndFrame())

    runner = PipelineRunner()
    await runner.run(task)

if __name__ == "__main__":
    asyncio.run(main())

Note the import pattern: the single pipecat-plugins-munsit package ships two importable modules  pipecat_plugins_munsit for the STT service (MunsitSTTService) and pipecat_plugins_faseeh for the TTS service (FaseehTTSService). This is exactly as documented in Munsit’s own Pipecat integration guide at the time of writing; if you hit an ImportError on either name, confirm you’re importing from the correct module rather than assuming both classes live in one.

Run it like any Python script:

python agent.py

Since the example auto-creates a Daily room via DailyRESTHelper, the terminal output (or Daily’s dashboard) will give you the room URL to join and test from a browser or the Daily Prebuilt UI.

‍

This is some text inside of a div block.

Heading

Lorem ipsum dolor sit amet, consectetur adipiscing elit. Suspendisse varius enim in eros elementum tristique. Duis cursus, mi quis viverra ornare, eros dolor interdum nulla, ut commodo diam libero vitae erat. Aenean faucibus nibh et justo cursus id rutrum lorem imperdiet. Nunc ut sem vitae risus tristique posuere.

Lorem ipsum dolor sit amet, consectetur adipiscing elit. Suspendisse varius enim in eros elementum tristique. Duis cursus, mi quis viverra ornare, eros dolor interdum nulla, ut commodo diam libero vitae erat. Aenean faucibus nibh et justo cursus id rutrum lorem imperdiet. Nunc ut sem vitae risus tristique posuere.

Lorem ipsum dolor sit amet, consectetur adipiscing elit. Suspendisse varius enim in eros elementum tristique. Duis cursus, mi quis viverra ornare, eros dolor interdum nulla, ut commodo diam libero vitae erat. Aenean faucibus nibh et justo cursus id rutrum lorem imperdiet. Nunc ut sem vitae risus tristique posuere.

Lorem ipsum dolor sit amet, consectetur adipiscing elit. Suspendisse varius enim in eros elementum tristique. Duis cursus, mi quis viverra ornare, eros dolor interdum nulla, ut commodo diam libero vitae erat. Aenean faucibus nibh et justo cursus id rutrum lorem imperdiet. Nunc ut sem vitae risus tristique posuere.

Step 3: Configure Text-to-Speech

FaseehTTSService takes the following constructor parameters. To pick a voice, browse Munsit’s Voice Library, listen to samples, and copy the voice ID:

Parameter Type Default Description
api_key str env MUNSIT_API_KEY Munsit API key
voice_id str ar-hijazi-female-2 Voice identifier
model str faseeh-v1-preview TTS model
stability float 0.5 Voice consistency (0.0–1.0)
speed float 1.0 Speech rate (0.7–1.2)
sample_rate int 48000 Output PCM rate requested from the API. 48000 is the engine’s native rate, so no downsampling or client-side resampling happens at that setting. Match your transport’s audio_out_sample_rate to it.
base_url str https://api.munsit.com/api/v1 API base URL

‍

You can change voice, model, speed, or stability mid-conversation by queueing a TTSUpdateSettingsFrame, rather than tearing down and recreating the service:

tts = FaseehTTSService(
api_key="your-api-key",
voice_id="ar-uae-male-1",  # Paste the copied voice ID here
aiohttp_session=session,
)

from pipecat.frames.frames import TTSUpdateSettingsFrame

# Switch voice
await task.queue_frame(TTSUpdateSettingsFrame(settings={"voice_id": "ar-emirati-male-1"}))

# Adjust speed and stability
await task.queue_frame(TTSUpdateSettingsFrame(settings={"speed": 1.1, "stability": 0.8}))

# Switch model
await task.queue_frame(TTSUpdateSettingsFrame(settings={"model": "faseeh-v2"}))

‍

Step 4: Speech-to-Text

Munsit’s Pipecat documentation is lighter on MunsitSTTService configuration than it is on the TTS side  the published example instantiates it with just an API key (MunsitSTTService(api_key=os.getenv("MUNSIT_API_KEY", ""))) and relies on its defaults for everything else. If your use case needs non-default STT behavior  a specific model, custom vocabulary, or tuned endpointing  check Munsit’s live API reference and the plugin’s own docstrings before assuming a parameter exists, rather than guessing at a name that matches the LiveKit plugin’s STT options.

‍

See how Munsit performs on real Arabic speech

Evaluate dialect coverage, noise handling, and in-region deployment on data that reflects your customers.
Explore

Step 5: Handle Errors

The plugin yields non-fatal ErrorFrame objects instead of raising exceptions, so your pipeline keeps running even if a single TTS request fails:

from pipecat.frames.frames import ErrorFrame

@task.event_handler("on_error")
async def on_error(task, error: ErrorFrame):
‍

HTTP Status Meaning Action
401 Invalid API key Check MUNSIT_API_KEY
402 Insufficient balance Add credits at app.munsit.com
404 Voice or model not found Check voice_id and model
429 Rate limit exceeded Reduce request frequency

FAQ

Does Munsit’s Pipecat plugin handle both Arabic speech recognition and Arabic speech synthesis?
Why are there two different import paths for one pip package?
Does the TTS service support streaming?

Powering the Future with AI

Join our newsletter for insights on cutting-edge technology built in the UAE
Thank you! Your submission has been received!
Oops! Something went wrong while submitting the form.
Last update :
October 5, 2026

How to Build an Arabic Voice Agent with Pipecat (2026 Guide)

How-To
Arabic Voice AI
Author
Sarra Turki
Rym Bachouche
5min read

Bring Arabic Voice AI to production

Native‑level Arabic STT & TTS
Built for GCC gov & enterprises
Sovereign and on‑prem deployment
Contact Sales
Thank you! Your submission has been received!
Oops! Something went wrong while submitting the form.

Key Takeaways

Pipecat simplifies real-time voice-agent development: Developers can build a pipeline connecting audio transport, Munsit STT, an LLM, and Munsit TTS to create conversational Arabic voice experiences.

Munsit supports the complete Arabic voice layer: The Pipecat plugin provides both speech recognition and speech synthesis, allowing developers to use Munsit for both sides of the conversation.

Voice output can be customized: Developers can select different voices and adjust speed, stability, sample rate, and models. These settings can also be updated while the conversation is running.

Streaming improves conversational flow: Faseeh TTS streams audio as it becomes available, allowing the agent to begin speaking without waiting for the entire response to finish rendering.

Error handling keeps the pipeline resilient: TTS failures generate non-fatal error frames, allowing the pipeline to continue running while developers log and respond to errors

Pipecat offers transport flexibility: While the guide uses Daily WebRTC, developers can use other supported transports while keeping Munsit’s STT and TTS processors in the pipeline.

Production deployments require regional considerations: Voice data, transcripts, cloned voices, and deployment environments may have specific privacy and compliance requirements in the UAE and Saudi Arabia.

The article shows developers how to build an Arabic voice agent using Pipecat, Munsit’s Arabic speech-to-text and text-to-speech services, and an LLM. It explains how audio moves through the pipeline—from the user’s microphone to Munsit STT, the LLM, Munsit TTS, and finally back to the user as streaming Arabic speech.

The guide covers installing the Munsit Pipecat plugin, setting up API credentials, creating the agent, configuring Daily WebRTC transport, and customizing TTS settings such as voice, speed, stability, and sample rate. It also explains how developers can update voice settings during an active conversation.

‍

How to Build an Arabic Voice Agent with Pipecat

A voice agent has to solve a pipeline problem before it solves a prompting problem: speech has to become text fast enough to feel conversational, a language model has to reason over that text, and the reply has to become speech again without a noticeable gap. For Arabic specifically, callers routinely mix Arabic and English mid-sentence, and a generic multilingual STT model handles that switch by treating it as two separate recognition tasks  producing seams and errors exactly where the conversation matters most.

This guide walks through building an Arabic voice agent on Pipecat  the open-source Python framework for real-time voice and multimodal conversational agents, created and maintained by Daily, Inc. with the Pipecat developer community  using Munsit’s pipecat-plugins-munsit package, which provides both Arabic speech-to-text (live WebSocket streaming) and text-to-speech (HTTP streaming) for Arabic, including Arabic-English code-switching, from a single vendor.

‍

Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor
Lorem ipsum dolor

Architecture: What You’re Building

Understanding the origins of AI hallucinations is the first step toward mitigating them. The phenomenon is not a single problem but rather a complex issue with multiple contributing factors.

1

Training Data Deficiencies

A Pipecat agent is built as a Pipeline of processors that frames of data move through in sequence. For a voice agent, that sequence is: microphone → transport → Munsit STT → LLM → Munsit TTS → transport → speaker. The caller speaks; the transport (this guide uses Daily’s WebRTC transport, the one documented in Munsit’s own Pipecat integration guide) captures the audio; Munsit’s STT service converts it to text; an LLM generates a reply; Munsit’s TTS service converts that reply to streaming Arabic audio  PCM16 at 24 kHz  and the transport plays it back. Pipecat’s TTSService base class aggregates LLM tokens into complete sentences before calling Munsit, so each sentence becomes one HTTP streaming request, with PCM16 chunks yielded back to the pipeline as they arrive.
‍

Prerequisites
‍

•             Python 3.9 or later

•             A Munsit account and an API key (generated from Munsit’s API Keys dashboard)

•             A Daily account and API key, if you use Daily as your WebRTC transport (Pipecat supports other transports too)

•             An LLM provider key (this guide uses OpenAI’s GPT-4o, but any Pipecat-supported LLM service will work)
‍

Step 1: Install and Authenticate
‍

pip install pipecat-plugins-munsit

Your Munsit API key is shown only once at creation  save it securely as the MUNSIT_API_KEY environment variable rather than hardcoding it. The plugin’s TTS service also expects a shared aiohttp session rather than opening its own connection per request:

import aiohttp
from pipecat_plugins_faseeh import FaseehTTSService

async with aiohttp.ClientSession() as session:
tts = FaseehTTSService(
    api_key="your-api-key",
        aiohttp_session=session,
)

Keep MUNSIT_API_KEY (and DAILY_API_KEY, OPENAI_API_KEY) out of version control; load them from environment variables or a .env file via python-dotenv in production.
‍

Step 2: Write the Agent


A complete Daily-transported agent auto-creates a Daily room, wires Munsit STT → GPT-4o → Munsit TTS, and greets the caller as soon as they join:

import asyncio
import os

import aiohttp
from dotenv import load_dotenv

from pipecat.audio.vad.silero import SileroVADAnalyzer
from pipecat.frames.frames import EndFrame, LLMMessagesUpdateFrame
from pipecat.pipeline.pipeline import Pipeline
from pipecat.pipeline.runner import PipelineRunner
from pipecat.pipeline.task import PipelineParams, PipelineTask
from pipecat.processors.aggregators.llm_context import LLMContext
from pipecat.processors.aggregators.llm_response_universal import (
    LLMContextAggregatorPair,
    LLMUserAggregatorParams,
)
from pipecat_plugins_munsit import MunsitSTTService
from pipecat.services.openai.llm import OpenAILLMService
from pipecat.transports.daily.transport import DailyParams, DailyTransport
from pipecat_plugins_faseeh import FaseehTTSService

load_dotenv(override=True)

async def main():
async with aiohttp.ClientSession() as session:
    # Auto-create a Daily room
    from pipecat.transports.daily.utils import DailyRESTHelper, DailyRoomParams

        daily_helper = DailyRESTHelper(
            daily_api_key=os.getenv("DAILY_API_KEY", ""),
            aiohttp_session=session,
    )
    room = await daily_helper.create_room(DailyRoomParams())
    token = await daily_helper.get_token(room.url)

    transport = DailyTransport(
            room.url,
        token,
        "Munsit Bot",
            DailyParams(
                audio_in_enabled=True,
                audio_out_enabled=True,
                audio_out_sample_rate=48000,
        ),
    )

    stt = MunsitSTTService(api_key=os.getenv("MUNSIT_API_KEY", ""))
    llm = OpenAILLMService(api_key=os.getenv("OPENAI_API_KEY", ""), model="gpt-4o")
    tts = FaseehTTSService(
        api_key=os.getenv("MUNSIT_API_KEY"),
            aiohttp_session=session,
    )

    messages = [
        {
            "role": "system",
            "content": "You are a helpful Arabic-speaking assistant. Respond in Arabic.",
        }
    ]
    context = LLMContext(messages=messages)
        context_aggregator = LLMContextAggregatorPair(
            context,
            user_params=LLMUserAggregatorParams(vad_analyzer=SileroVADAnalyzer()),
    )

    pipeline = Pipeline([
            transport.input(),
        stt,
            context_aggregator.user(),
        llm,
        tts,
            transport.output(),
            context_aggregator.assistant(),
    ])

    task = PipelineTask(pipeline, params=PipelineParams(allow_interruptions=True))

    @transport.event_handler("on_first_participant_joined")
    async def on_joined(transport, participant):
        await task.queue_frames([LLMMessagesUpdateFrame(messages, run_llm=True)])

    @transport.event_handler("on_participant_left")
    async def on_left(transport, participant, reason):
        await task.queue_frame(EndFrame())

    runner = PipelineRunner()
    await runner.run(task)

if __name__ == "__main__":
    asyncio.run(main())

Note the import pattern: the single pipecat-plugins-munsit package ships two importable modules  pipecat_plugins_munsit for the STT service (MunsitSTTService) and pipecat_plugins_faseeh for the TTS service (FaseehTTSService). This is exactly as documented in Munsit’s own Pipecat integration guide at the time of writing; if you hit an ImportError on either name, confirm you’re importing from the correct module rather than assuming both classes live in one.

Run it like any Python script:

python agent.py

Since the example auto-creates a Daily room via DailyRESTHelper, the terminal output (or Daily’s dashboard) will give you the room URL to join and test from a browser or the Daily Prebuilt UI.
‍

2

Training Data Deficiencies

The most significant contributor to AI hallucinations is the data on which the models are trained. LLMs learn from vast datasets scraped from the internet, which contain a mixture of factual information, opinions, misinformation, and biases. Several specific data-related issues can lead to hallucinations:

Enterprise Use Cases for Arabic Voice AI in 2025

The move to dialect-aware Arabic ASR is unlocking a new wave of enterprise applications across the GCC and MENA regions. Organizations are moving beyond basic transcription to sophisticated Arabic speech analytics.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

Step 3: Configure Text-to-Speech

Understanding the origins of AI hallucinations is the first step toward mitigating them. The phenomenon is not a single problem but rather a complex issue with multiple contributing factors.

1

Training Data Deficiencies

FaseehTTSService takes the following constructor parameters. To pick a voice, browse Munsit’s Voice Library, listen to samples, and copy the voice ID:

Parameter Type Default Description
api_key str env MUNSIT_API_KEY Munsit API key
voice_id str ar-hijazi-female-2 Voice identifier
model str faseeh-v1-preview TTS model
stability float 0.5 Voice consistency (0.0–1.0)
speed float 1.0 Speech rate (0.7–1.2)
sample_rate int 48000 Output PCM rate requested from the API. 48000 is the engine’s native rate, so no downsampling or client-side resampling happens at that setting. Match your transport’s audio_out_sample_rate to it.
base_url str https://api.munsit.com/api/v1 API base URL

‍

You can change voice, model, speed, or stability mid-conversation by queueing a TTSUpdateSettingsFrame, rather than tearing down and recreating the service:

tts = FaseehTTSService(
api_key="your-api-key",
voice_id="ar-uae-male-1",  # Paste the copied voice ID here
aiohttp_session=session,
)

from pipecat.frames.frames import TTSUpdateSettingsFrame

# Switch voice
await task.queue_frame(TTSUpdateSettingsFrame(settings={"voice_id": "ar-emirati-male-1"}))

# Adjust speed and stability
await task.queue_frame(TTSUpdateSettingsFrame(settings={"speed": 1.1, "stability": 0.8}))

# Switch model
await task.queue_frame(TTSUpdateSettingsFrame(settings={"model": "faseeh-v2"}))

‍

2

Training Data Deficiencies

The most significant contributor to AI hallucinations is the data on which the models are trained. LLMs learn from vast datasets scraped from the internet, which contain a mixture of factual information, opinions, misinformation, and biases. Several specific data-related issues can lead to hallucinations:

Enterprise Use Cases for Arabic Voice AI in 2025

The move to dialect-aware Arabic ASR is unlocking a new wave of enterprise applications across the GCC and MENA regions. Organizations are moving beyond basic transcription to sophisticated Arabic speech analytics.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

Building better AI systems takes the right approach

We help with custom solutions, data pipelines, and Arabic intelligence.

Step 4: Speech-to-Text

Understanding the origins of AI hallucinations is the first step toward mitigating them. The phenomenon is not a single problem but rather a complex issue with multiple contributing factors.

1

Training Data Deficiencies

Munsit’s Pipecat documentation is lighter on MunsitSTTService configuration than it is on the TTS side  the published example instantiates it with just an API key (MunsitSTTService(api_key=os.getenv("MUNSIT_API_KEY", ""))) and relies on its defaults for everything else. If your use case needs non-default STT behavior  a specific model, custom vocabulary, or tuned endpointing  check Munsit’s live API reference and the plugin’s own docstrings before assuming a parameter exists, rather than guessing at a name that matches the LiveKit plugin’s STT options.

‍

2

Training Data Deficiencies

The most significant contributor to AI hallucinations is the data on which the models are trained. LLMs learn from vast datasets scraped from the internet, which contain a mixture of factual information, opinions, misinformation, and biases. Several specific data-related issues can lead to hallucinations:

Enterprise Use Cases for Arabic Voice AI in 2025

The move to dialect-aware Arabic ASR is unlocking a new wave of enterprise applications across the GCC and MENA regions. Organizations are moving beyond basic transcription to sophisticated Arabic speech analytics.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

Step 5: Handle Errors

Understanding the origins of AI hallucinations is the first step toward mitigating them. The phenomenon is not a single problem but rather a complex issue with multiple contributing factors.

1

Training Data Deficiencies

The plugin yields non-fatal ErrorFrame objects instead of raising exceptions, so your pipeline keeps running even if a single TTS request fails:

from pipecat.frames.frames import ErrorFrame

@task.event_handler("on_error")
async def on_error(task, error: ErrorFrame):
‍

HTTP Status Meaning Action
401 Invalid API key Check MUNSIT_API_KEY
402 Insufficient balance Add credits at app.munsit.com
404 Voice or model not found Check voice_id and model
429 Rate limit exceeded Reduce request frequency
2

Training Data Deficiencies

The most significant contributor to AI hallucinations is the data on which the models are trained. LLMs learn from vast datasets scraped from the internet, which contain a mixture of factual information, opinions, misinformation, and biases. Several specific data-related issues can lead to hallucinations:

Enterprise Use Cases for Arabic Voice AI in 2025

The move to dialect-aware Arabic ASR is unlocking a new wave of enterprise applications across the GCC and MENA regions. Organizations are moving beyond basic transcription to sophisticated Arabic speech analytics.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

Troubleshooting

Understanding the origins of AI hallucinations is the first step toward mitigating them. The phenomenon is not a single problem but rather a complex issue with multiple contributing factors.

1

Training Data Deficiencies

Symptom Fix
No audio output Verify MUNSIT_API_KEY is set and valid, that voice_id exists in the Voice Library, and that the pipeline sample rate matches the plugin’s (48000 Hz default).
High latency The plugin already uses HTTP streaming for lowest latency. Check connectivity to api.munsit.com, or try a voice with faster generation characteristics.
Import errors Make sure both pipecat-ai and pipecat-plugins-munsit are installed, and that you’re importing FaseehTTSService from pipecat_plugins_faseeh and MunsitSTTService from pipecat_plugins_munsit — not from a single combined module. Munsit’s documentation lists a minimum Pipecat version of 0.0.100 at the time of writing; confirm against the plugin’s current PyPI listing if you hit a version conflict.

‍

Support channels: the pipecat-plugins-munsit package on PyPI, GitHub Issues, the Pipecat community (Daily’s Discord), and Munsit support directly. The plugin is Apache 2.0 licensed.

2

Training Data Deficiencies

The most significant contributor to AI hallucinations is the data on which the models are trained. LLMs learn from vast datasets scraped from the internet, which contain a mixture of factual information, opinions, misinformation, and biases. Several specific data-related issues can lead to hallucinations:

Enterprise Use Cases for Arabic Voice AI in 2025

The move to dialect-aware Arabic ASR is unlocking a new wave of enterprise applications across the GCC and MENA regions. Organizations are moving beyond basic transcription to sophisticated Arabic speech analytics.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

UAE and Saudi Compliance Considerations for Voice Agents

Understanding the origins of AI hallucinations is the first step toward mitigating them. The phenomenon is not a single problem but rather a complex issue with multiple contributing factors.

1

Training Data Deficiencies

A production voice agent processes live customer voice data, which carries specific regulatory considerations in the UAE and Saudi Arabia beyond the technical build:
‍

Voice is personal data. Under the UAE’s Federal Decree-Law No. 45/2021 (PDPL) and Saudi Arabia’s PDPL (enforced since September 2024), voice recordings and the transcripts and derived data (sentiment, intent) generated from a voice agent conversation are personal data. Confirm the legal basis for processing  typically consent or legitimate business interest with proper notice  before deploying a customer-facing agent, and document where that audio and its derived transcripts are processed and stored.
‍

Disclosing that a caller is talking to AI isn’t currently mandated by a specific UAE statute, but it’s good practice regardless. The UAE Charter for the Development and Use of Artificial Intelligence establishes transparency as a national AI principle  building “clear understanding of AI and how systems operate”  without spelling out a specific disclosure requirement for conversational or voice agents. Absent an explicit mandate, disclosing early in the conversation that the caller is speaking with an AI assistant (easy to add to the system prompt or an opening TTS line in Step 2) is a reasonable practice consistent with that transparency principle.
‍

Voice cloning requires separate, explicit consent. If voice_id in your TTS configuration is a cloned voice of a real person  rather than a stock voice from the Voice Library  using that clone commercially requires documented, explicit consent from that person, under both the PDPL’s treatment of voice as personal data and the UAE’s Federal Decree-Law No. 34/2021 (Cybercrimes Law), which covers unauthorized use of someone’s likeness or voice.
‍

Sovereign deployment matters for regulated sectors. Government, banking, and healthcare voice agents often need audio processing to stay within a defined jurisdiction or air-gapped environment. Munsit documents cloud, sovereign VPC, on-premises, and on-device deployment options beyond the standard cloud API shown in this guide  confirm which deployment model fits your sector’s requirements before architecture decisions assume cloud-only.
‍

This section provides general information, not legal advice. Consult qualified legal counsel for compliance decisions specific to your deployment and jurisdiction.

‍

2

Training Data Deficiencies

The most significant contributor to AI hallucinations is the data on which the models are trained. LLMs learn from vast datasets scraped from the internet, which contain a mixture of factual information, opinions, misinformation, and biases. Several specific data-related issues can lead to hallucinations:

Enterprise Use Cases for Arabic Voice AI in 2025

The move to dialect-aware Arabic ASR is unlocking a new wave of enterprise applications across the GCC and MENA regions. Organizations are moving beyond basic transcription to sophisticated Arabic speech analytics.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

Understanding the origins of AI hallucinations is the first step toward mitigating them. The phenomenon is not a single problem but rather a complex issue with multiple contributing factors.

1

Training Data Deficiencies

2

Training Data Deficiencies

The most significant contributor to AI hallucinations is the data on which the models are trained. LLMs learn from vast datasets scraped from the internet, which contain a mixture of factual information, opinions, misinformation, and biases. Several specific data-related issues can lead to hallucinations:

Enterprise Use Cases for Arabic Voice AI in 2025

The move to dialect-aware Arabic ASR is unlocking a new wave of enterprise applications across the GCC and MENA regions. Organizations are moving beyond basic transcription to sophisticated Arabic speech analytics.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

Arabic speech technology is rapidly advancing in 2025, driven by massive multilingual models and new Arabic-centric foundation models.

FAQ
Does Munsit’s Pipecat plugin handle both Arabic speech recognition and Arabic speech synthesis?
Why are there two different import paths for one pip package?
Does the TTS service support streaming?
Do I need Daily specifically, or can I use a different transport?
What happens if a TTS request fails mid-conversation?
How does this compare to Munsit’s LiveKit plugin?

Bring Arabic Voice AI to production

Native‑level Arabic STT & TTS
Built for GCC gov & enterprises
Sovereign and on‑prem deployment
Contact Sales
Thank you! Your submission has been received!
Oops! Something went wrong while submitting the form.

Start free.  
Pay when you are ready.

10,000 credits. Test Munsit with your own audio, in your own dialect, and see the accuracy for yourself.